Construct-Rating Content Validation: Hinkin-Tracey to Colquitt
Source:vignettes/construct-rating-validity.Rmd
construct-rating-validity.RmdWhat the rating workflow asks
The Hinkin and Tracey (1999) content-rating procedure asks judges to evaluate how well each item corresponds to each construct definition under consideration. The typical design is fully crossed within judges: the same judge rates an item against the intended definition and against one or more orbiting definitions.
That design provides two complementary kinds of evidence:
- Definitional correspondence: does the item strongly match its intended construct?
- Definitional distinctiveness: does it match the intended construct more strongly than plausible orbiting constructs?
contentvalidR keeps those questions separate rather than
reducing the study to a single coefficient.
Example data
rating_dat <- expand.grid(
  item = c("A1", "A2", "A3", "B1"),
  rater = 1:24,
  construct = c("A", "B", "C")
)
rating_dat$target_construct <- ifelse(rating_dat$item == "B1", "B", "A")

rating_dat$rating <- ifelse(
  rating_dat$construct == rating_dat$target_construct,
  pmin(5, pmax(1, round(rnorm(nrow(rating_dat), 4.4, .6)))),
  pmin(5, pmax(1, round(rnorm(nrow(rating_dat), 2.2, .8))))
)
Each item-judge combination appears once for every construct definition. A duplicated item-rater-construct row is treated as a data error.
HTC: definitional correspondence
Following Colquitt et al. (2019), the Hinkin-Tracey correspondence index is
where
is the number of response anchors when ratings use a
1-to-
scale. contentvalidR can also accept an equally spaced
integer scale such as 0-to-4; it shifts that scale internally to the
equivalent 1-to-5 anchor metric before computing HTC.
htc(rating_dat, scale_min = 1, scale_max = 5)
#> <contentvalid_htc> Hinkin-Tracey correspondence (HTC)
#> Colquitt et al. (2019).
#>
#>   Item  Target  Judges  Target mean  HTC
#>   A1    A           24         4.38  .88
#>   A2    A           24         4.46  .89
#>   A3    A           24         4.42  .88
#>   B1    B           24         4.58  .92
#>
#> HTC expresses the mean target rating as a share of the 5-point scale.
#>
#> See as.data.frame(x) for the unrounded values.
Higher HTC means stronger correspondence with the intended definition. Because the lowest rating still counts as one point, HTC cannot reach 0: it runs from to 1, so from .20 to 1 on a five-point scale.
HTD: definitional distinctiveness
HTD compares intended-definition ratings with orbiting-definition ratings:
The average runs over every judge and every orbiting definition, so HTD is the intended definition’s average lead over all the orbiting definitions, not its lead over the closest one. It ranges from -1 to 1. Positive values favor the intended definition; negative values indicate that orbiting definitions are rated more highly on average.
htd(rating_dat, scale_min = 1, scale_max = 5)
#> <contentvalid_htd> Hinkin-Tracey distinctiveness (HTD)
#> Colquitt et al. (2019).
#>
#>   Item  Target  Judges  Target mean  Competitor  Competitor mean  HTD
#>   A1    A           24         4.38  B                      2.38  .56
#>   A2    A           24         4.46  B                      2.00  .63
#>   A3    A           24         4.42  C                      2.25  .55
#>   B1    B           24         4.58  C                      2.17  .61
#>
#> Competitor: the other construct with the highest mean rating. HTD itself
#> averages the gap over every other construct.
#>
#> See as.data.frame(x) for the unrounded values.
The item-level table also identifies the strongest orbiting competitor. That is often more useful for revision than merely knowing that distinctiveness is weak.
Repeated-measures item screening
Hinkin and Tracey (1999) analyzed these ratings with a one-way ANOVA
and Duncan’s multiple range test, treating the definitions as
independent groups. The same judges provide multiple construct ratings,
though, so those observations are not independent. MacKenzie et
al. (2011) recommend a one-way repeated-measures ANOVA for this task,
followed, when its F is significant, by a planned contrast of
the intended definition against the others. anova_content()
uses that repeated-measures form for the standard fully crossed design
and follows it with planned paired comparisons of the intended
definition against every orbiting definition.
An item is retained when the omnibus test and then its contrasts
pass, which follows their sequence. Some details are this package’s
choices, not taken from either source: the Greenhouse-Geisser (1959)
corrected p is the screening p of the omnibus test;
there is one one-sided contrast for each orbiting definition, and every
one must pass, where MacKenzie et al. describe a single contrast; the
contrasts are not adjusted for their number unless you ask
(adjust = "holm"); and the tests need at least two judges
who rated the item against every definition.
aov_out <- anova_content(rating_dat, design = "within")
aov_out
#> <contentvalid_anova> Content-validity ANOVA
#> Adapted from Hinkin and Tracey (1999) and MacKenzie et al. (2011).
#>
#>   Item Target Judges F test                       p Partial eta^2 Contrast p Met
#>   A1   A          24 F(1.98, 45.65) = 72.64  < .001           .76     < .001 yes
#>   A2   A          24 F(1.62, 37.22) = 105.82 < .001           .82     < .001 yes
#>   A3   A          24 F(2.00, 45.97) = 82.25  < .001           .78     < .001 yes
#>   B1   B          24 F(1.85, 42.61) = 108.29 < .001           .82     < .001 yes
#>
#> Within-judge omnibus tests are Greenhouse-Geisser corrected, which reduces
#> their degrees of freedom.
#> Contrast p: the largest p among the planned contrasts, each one-sided (the
#> intended construct rated above one of the others), at alpha = .05 with no
#> adjustment for their number. It is -- when a contrast has no p because every
#> judge rated the two constructs the same. Met: whether every contrast passed.
#> attr(x, "contrasts") holds each one.
#>
#> See as.data.frame(x) for the unrounded values.
The omnibus F test asks whether the item’s mean ratings differ
somewhere across definitions. The planned contrasts ask the more direct
content-validity question: is the target mean higher than each orbiting
mean? attr(aov_out, "contrasts") holds each contrast at
full precision. Rounded for reading, with p values written the
APA way:
contrasts <- attr(aov_out, "contrasts")
shown <- contrasts[c("item", "target", "competitor", "mean_diff", "t", "df",
                     "p", "dz", "pass")]
shown[c("mean_diff", "t", "dz")] <- round(shown[c("mean_diff", "t", "dz")], 2)
shown$p <- ifelse(shown$p < .001, "< .001",
                  sub("^0", "", sprintf("%.3f", shown$p)))
shown
#>   item target competitor mean_diff     t df      p   dz pass
#> 1   A1      A          B      2.00  9.59 23 < .001 1.96 TRUE
#> 2   A1      A          C      2.46 11.34 23 < .001 2.31 TRUE
#> 3   A2      A          B      2.46 10.55 23 < .001 2.15 TRUE
#> 4   A2      A          C      2.58 17.64 23 < .001 3.60 TRUE
#> 5   A3      A          B      2.21 11.07 23 < .001 2.26 TRUE
#> 6   A3      A          C      2.17 11.02 23 < .001 2.25 TRUE
#> 7   B1      B          A      2.50 13.13 23 < .001 2.68 TRUE
#> 8   B1      B          C      2.42 14.27 23 < .001 2.91 TRUE
mean_diff is the target mean less the competitor mean,
t and df the paired t test, and
dz the mean difference divided by the standard deviation of
the differences. p is one-sided, and pass says
whether the contrast met alpha, after an adjustment for their number
when one was asked for (p_adj).
With more than two construct definitions, the conventional
repeated-measures F test assumes sphericity. contentvalidR
prints the Greenhouse-Geisser corrected test, whose degrees of freedom
are fractional; as.data.frame(aov_out)$p holds the
uncorrected p value. The planned target-versus-orbiting
comparisons are important diagnostic evidence rather than decorative
post-hoc tests.
Recommended workflow
fit <- rating_validity(
  rating_dat,
  scale_min = 1,
  scale_max = 5
)
fit
#> <contentvalid_rating> Construct-rating analysis
#> Items: 4 | Judges: 24 | Target constructs: 2 | Constructs rated: 3
#> Design: within-judge ratings on a 1 to 5 scale
#> Test: one-way repeated-measures ANOVA (Greenhouse-Geisser corrected omnibus p)
#> plus planned paired target-versus-orbiting contrasts; planned-contrast
#> adjustment: none.
#> Retain: the omnibus p and every contrast p at or below alpha = .05. The
#> contrasts are one-sided: the intended construct rated above every other
#> construct.
#> Judges: naive, meaning drawn from the kind of people who will answer the
#> items.
#>
#> 4 of 4 items meet the full item-level screening criterion.
#>
#> Item-level evidence
#>   Item  Target  Decision  Judges  HTC  HTD  Omnibus p  Contrast p  Competitor
#>   A1    A       Retain        24  .88  .56     < .001      < .001  B
#>   A2    A       Retain        24  .89  .63     < .001      < .001  B
#>   A3    A       Retain        24  .88  .55     < .001      < .001  C
#>   B1    B       Retain        24  .92  .61     < .001      < .001  C
#>
#>   Judges: the number who rated the item against every construct. Omnibus p: do
#>   the item's ratings differ across constructs (Greenhouse-Geisser corrected).
#>   Contrast p: the largest p among the planned target-versus-orbiting
#>   contrasts, so every contrast is at or below it.
#>
#> Scale-level Colquitt benchmarks
#>   Target  Items  Mean HTC  HTC level    Mean HTD  HTD level
#>   A           3       .88  Strong            .58  Very Strong
#>   B           1       .92  Very Strong       .61  Very Strong
#>   Benchmark set: Overall (not correlation-normed)
#>
#>   Colquitt labels are empirical percentile norms for scale-level HTC and HTD
#>   averages, not universal cutoffs. HTC is an average rating and HTD is a
#>   difference between ratings, so they sit on different scales with different
#>   typical values. A high HTC can be labeled Weak in the same analysis where a
#>   much smaller HTD is labeled Very Strong. Compare each index against its own
#>   benchmark, never against the other index's number.
#>
#> What these columns mean
#>   HTC -- Hinkin-Tracey Correspondence. Mean rating against the intended
#>       definition, divided by the number of scale points (1/points to 1).
#>   HTD -- Hinkin-Tracey Distinctiveness. How far that rating exceeds the other
#>       constructs' ratings on average, as a share of the scale (usually small).
#>
#> What the decisions mean
#>   Retain -- its ratings differed across constructs (the omnibus test) and the
#>       intended construct was rated above every other (every planned contrast).
#>
#>   Full definitions: contentvalid_glossary(). To hide this key:
#>   options(contentvalidR.show_key = FALSE).
#>
#> A flag for review is not an automatic deletion decision. Consider construct
#> definitions, item wording, orbiting-construct choice, domain coverage, and
#> qualitative judge feedback.
#>
#> See summary(x) for the flagged items and content_report(x) for an APA table.
summary(fit)
#> <contentvalid_rating summary> Construct-rating analysis
#> Retain: 4 of 4 | Review: 0 of 4
#>
#> Scale-level evidence
#>   Target  Items  Retain  Review  Mean HTC  HTC level    Mean HTD  HTD level
#>   A           3       3       0       .88  Strong            .58  Very Strong
#>   B           1       1       0       .92  Very Strong       .61  Very Strong
#>
#>   HTC = Hinkin-Tracey correspondence; HTD = Hinkin-Tracey distinctiveness
#>   (Colquitt et al., 2019).
#>   A: Mean HTC falls in the Strong band and mean HTD in the Very Strong band of
#>     published scales (Colquitt et al., 2019).
#>   B: Mean HTC and mean HTD both fall in the Very Strong band of published
#>     scales (Colquitt et al., 2019).
#>
#> All analyzed items met the item-level inferential screening criterion.
#>
#> Interpret these results alongside theory, domain coverage, and qualitative
#> feedback. The analysis does not by itself establish comprehensiveness or the
#> full content-validity argument.
#>
#> See summary(x)$reviewed_items for the flagged items as a data frame.
The item-level recommendation has deliberately limited meaning:
- Retain: the item cleared the package’s inferential screening rule in this pretest: its omnibus p and every contrast p are at or below alpha.
- Review: the full screening rule was not met; inspect wording, construct overlap, and judge feedback.
- Insufficient data: fewer than two judges rated the item against every definition, so the repeated-measures comparison cannot be made. Its HTD, which rests on those judges, is left out of the scale’s mean HTD. Its HTC stays in the scale’s mean HTC when at least two judges rated the item against its intended definition.
Review is not an instruction to delete an item. Content
coverage can be harmed by mechanical item deletion.
Scale-level Colquitt norms
Colquitt et al. (2019) created empirical norms from
scale-level averages of HTC and HTD across 112
published scales. rating_validity() therefore averages item
HTC/HTD within each target scale before assigning those descriptive
normative labels.
scale_means <- fit$scale_summary[, c("target", "n_items", "mean_htc",
                                     "htc_strength", "mean_htd",
                                     "htd_strength")]
scale_means[c("mean_htc", "mean_htd")] <-
  round(scale_means[c("mean_htc", "mean_htd")], 2)
scale_means
#>   target n_items mean_htc htc_strength mean_htd htd_strength
#> 1      A       3     0.88       Strong     0.58  Very Strong
#> 2      B       1     0.92  Very Strong     0.61  Very Strong
colquitt_benchmarks("htc")
#> <contentvalid_colquitt_norms> Benchmarks for HTC
#> Colquitt et al. (2019). Benchmark set: Overall (not correlation-normed).
#>
#>   Band         Percentile  Minimum
#>   Very Strong  80th-99th       .91
#>   Strong       60th-79th       .87
#>   Moderate     40th-59th       .84
#>   Weak         20th-39th       .60
#>   Lack of      0th-19th       none
#>
#> A scale-level mean at or above a band's minimum falls in that band. The bands
#> are percentiles of published scales, not validity cutoffs.
#>
#> See as.data.frame(x) for the unrounded values.
colquitt_benchmarks("htd")
#> <contentvalid_colquitt_norms> Benchmarks for HTD
#> Colquitt et al. (2019). Benchmark set: Overall (not correlation-normed).
#>
#>   Band         Percentile  Minimum
#>   Very Strong  80th-99th       .35
#>   Strong       60th-79th       .27
#>   Moderate     40th-59th       .18
#>   Weak         20th-39th       .04
#>   Lack of      0th-19th       none
#>
#> A scale-level mean at or above a band's minimum falls in that band. The bands
#> are percentiles of published scales, not validity cutoffs.
#>
#> See as.data.frame(x) for the unrounded values.
The overall bands are empirical percentile standing, not universal validity cutoffs. If the average correlation between a focal scale and its orbiting scales is known, correlation-conditional norms can be requested:
conditional <- rating_validity(
  rating_dat,
  orbiting_r = c(A = .42, B = .55)
)
conditional$scale_summary[, c("target", "orbiting_r", "htc_strength",
                              "htd_strength", "benchmark_set")]
#>   target orbiting_r htc_strength htd_strength benchmark_set
#> 1      A       0.42     Moderate  Very Strong      moderate
#> 2      B       0.55  Very Strong  Very Strong      stronger
A given level of distinctiveness can be more impressive when the focal and orbiting constructs are known to correlate strongly.
Naive versus expert judges
Colquitt et al.’s normative distributions were developed using naive judges representative of substantive target populations. Their paper cautions against applying those norms to expert panels. The package therefore separates calculation from norm applicability:
expert_scale <- rating_validity(rating_dat, judge_type = "expert")$scale_summary[
  , c("target", "mean_htc", "htc_strength", "mean_htd", "htd_strength")]
expert_scale[c("mean_htc", "mean_htd")] <-
  round(expert_scale[c("mean_htc", "mean_htd")], 2)
expert_scale
#>   target mean_htc htc_strength mean_htd htd_strength
#> 1      A     0.88         <NA>     0.58         <NA>
#> 2      B     0.92         <NA>     0.61         <NA>
HTC/HTD are still computed, but the Colquitt labels are suppressed.
print() and summary() leave out the columns
that would hold them; the stored table, shown here with its means
rounded, keeps them as NA.
Missing ratings
For HTD and repeated-measures inference, a judge must have a usable rating for every construct definition presented for that item. Incomplete profiles are excluded itemwise and counted explicitly in the output. This preserves the paired design rather than quietly treating incomplete repeated observations as independent data.
Plotting
The original one-index views remain available:
plot(fit, metric = "htc")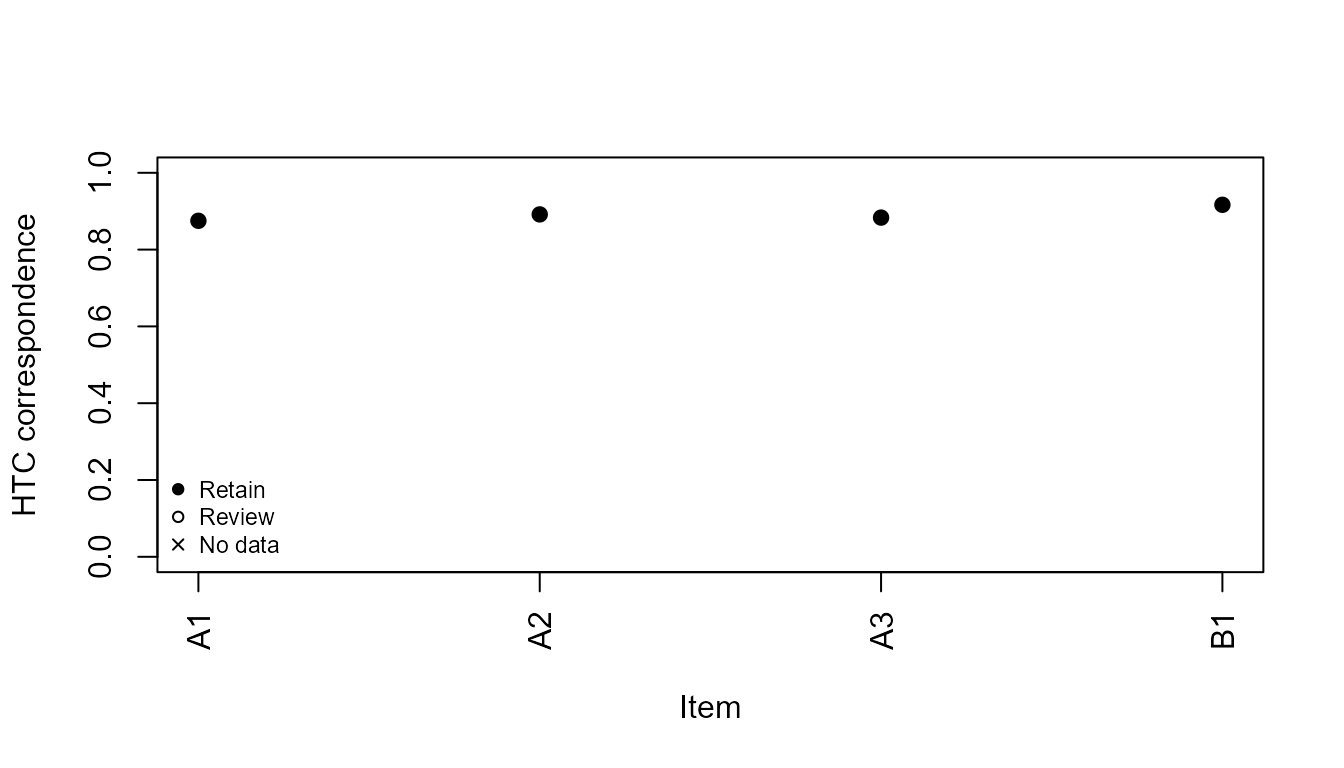
plot(fit, metric = "htd")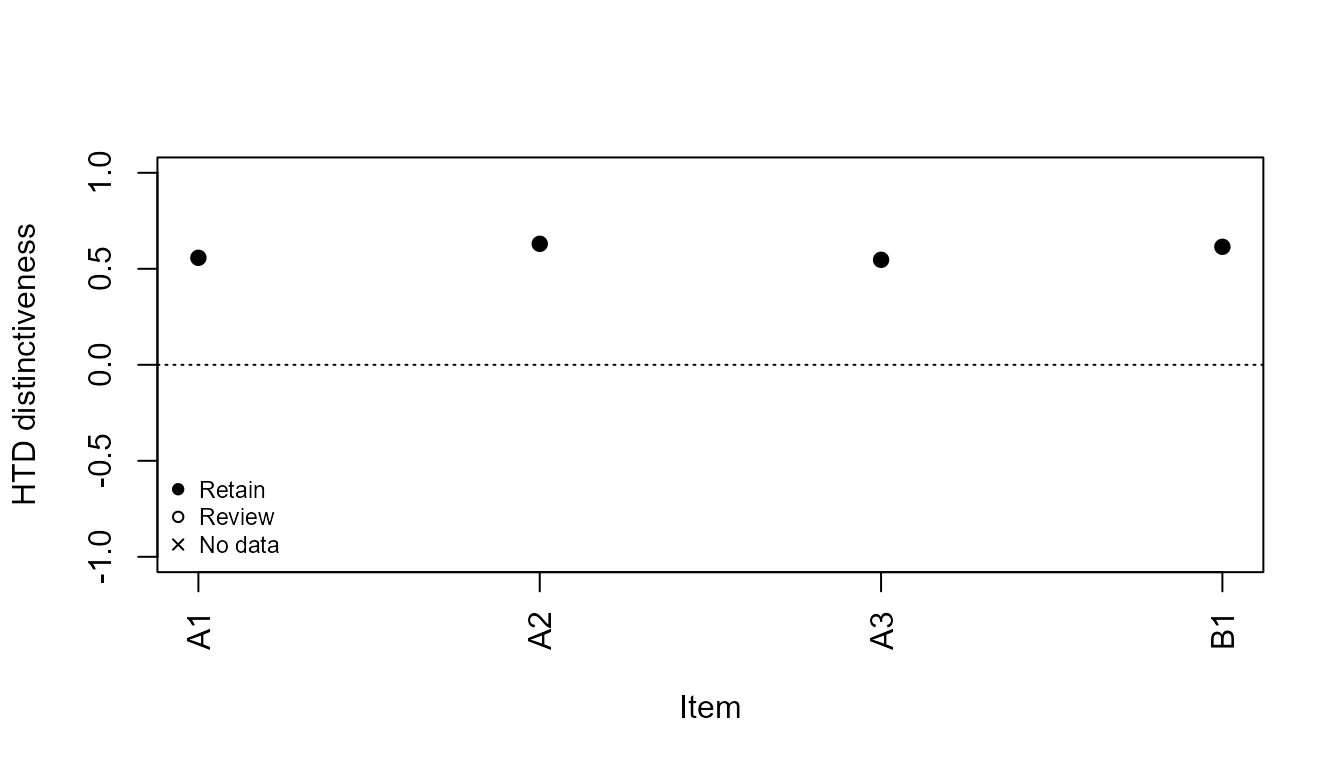
A correspondence-distinctiveness evidence map displays HTC and HTD together:
plot(fit, type = "map")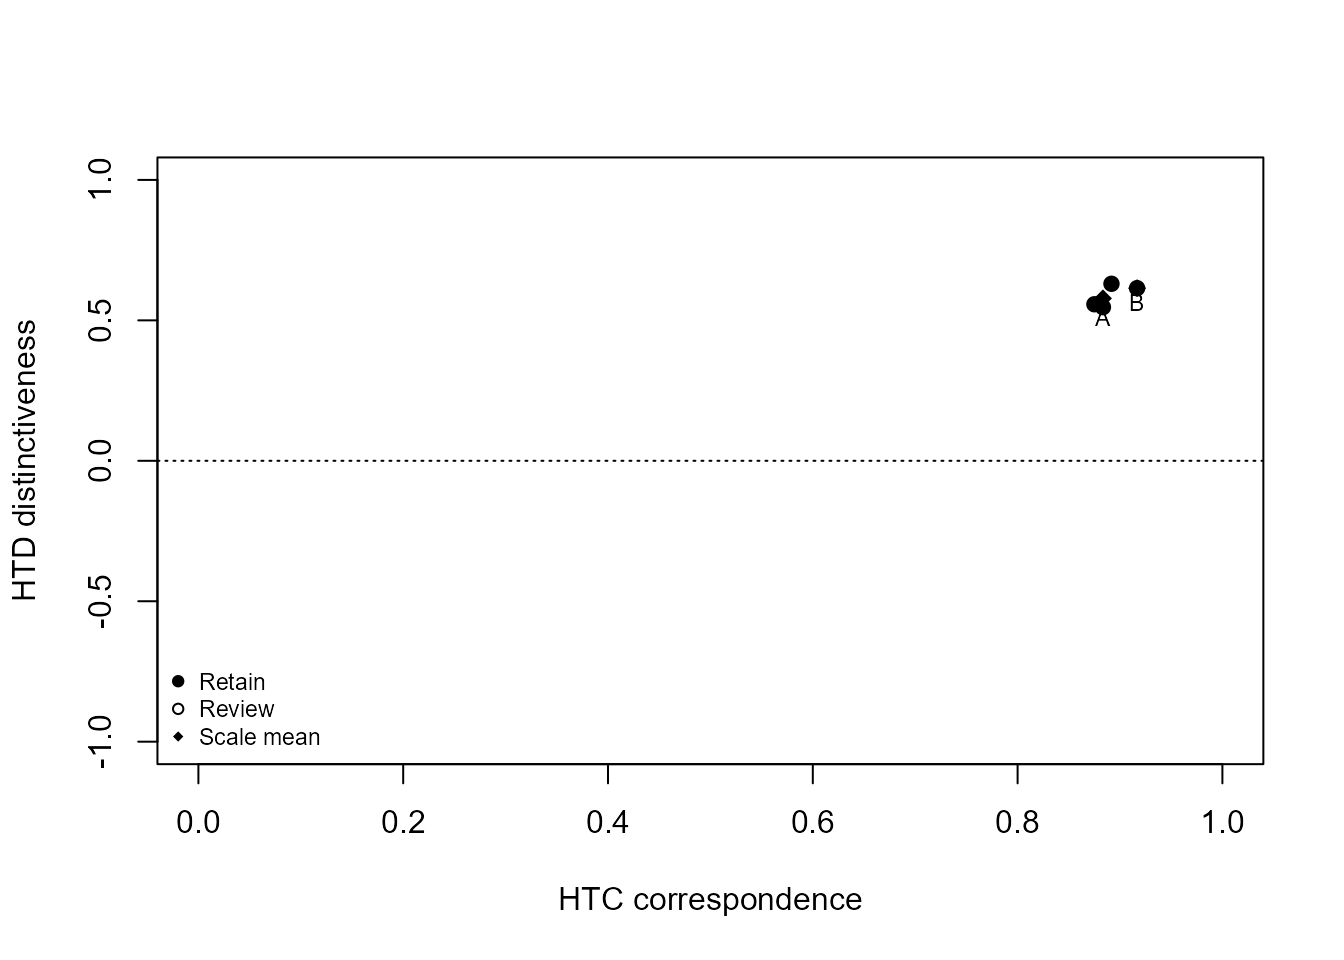
Target-scale averages are shown as triangles and items needing review are labeled by default. As with the item-sort map, Colquitt norm regions are not drawn across individual items because those benchmarks were constructed from scale averages.
The target-versus-competitor gap plot makes the Hinkin-Tracey mean-rating logic more directly visible:
plot(fit, type = "profile")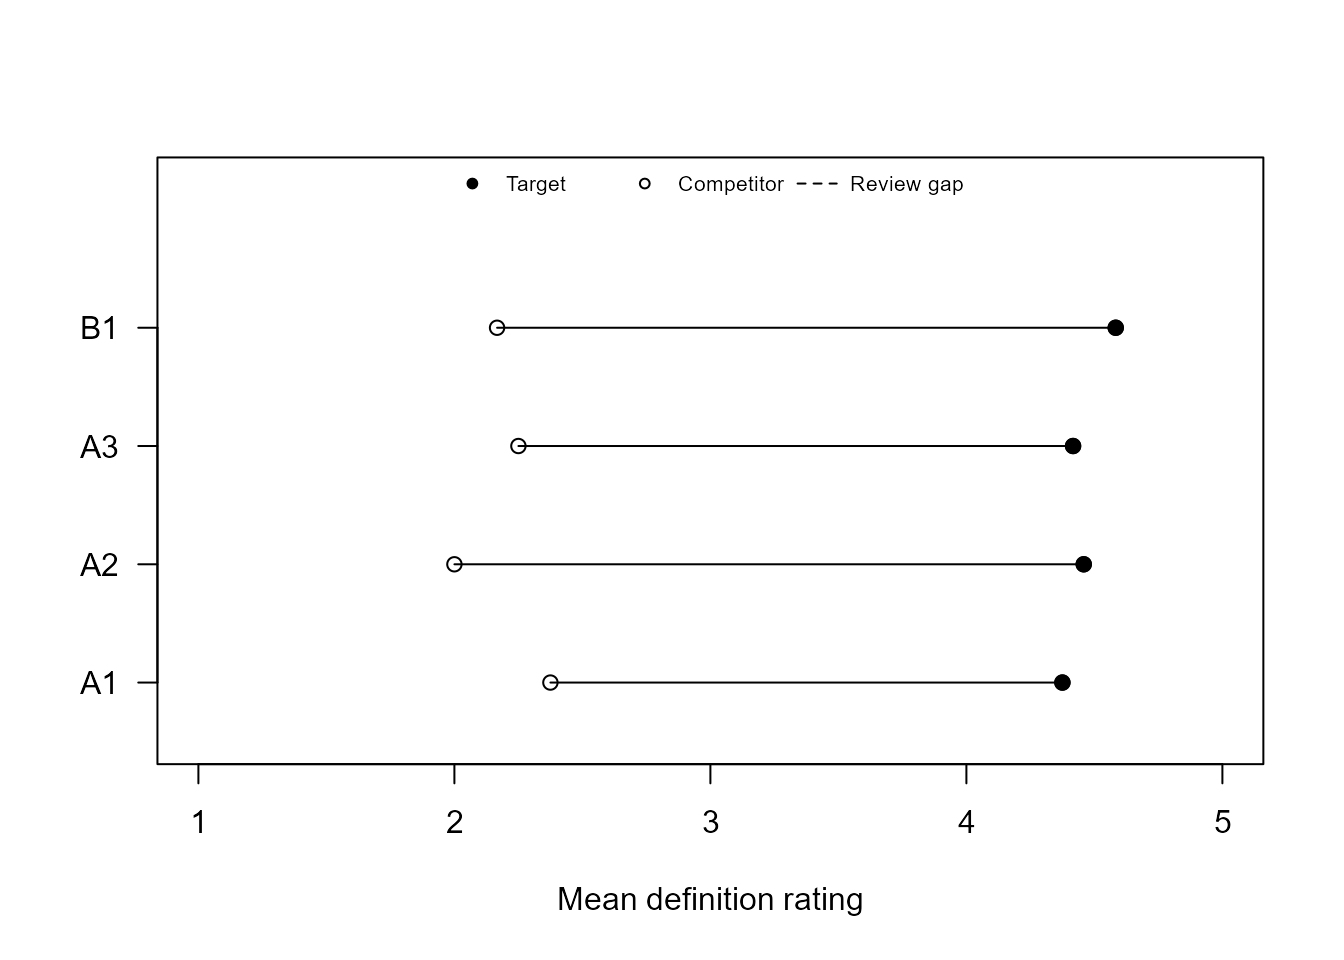
Filled points are intended-definition means, open points are the strongest orbiting-definition means, and the connecting segment is the gap between them. Both means come from the judges who rated the item against every definition, so the two ends of a segment describe the same judges. A reversed segment immediately identifies an item whose strongest competitor outrates its intended definition. An item with too few complete judges for a decision is marked with a cross and has no segment. This is a graphical extension of the mean-rating tables used in the original procedure, not a new statistical cutoff.
Reporting
A useful report should identify:
- the construct definitions and orbiting constructs shown to judges;
- the judge population and recruitment method;
- the response anchors and rating instructions;
- item-level HTC, HTD, repeated-measures omnibus results, and planned contrasts;
- the strongest orbiting competitor for items needing review;
- target-scale mean HTC/HTD and the norm set used, if applicable; and
- qualitative feedback and substantive decisions made after the pretest.
The quantitative analysis is evidence about definitional correspondence and distinctiveness. It does not by itself demonstrate that the item pool comprehensively samples the full construct domain.
References
Colquitt, J. A., Sabey, T. B., Rodell, J. B., & Hill, E. T. (2019). Content validation guidelines: Evaluation criteria for definitional correspondence and definitional distinctiveness. Journal of Applied Psychology, 104(10), 1243–1265. https://doi.org/10.1037/apl0000406
Greenhouse, S. W., & Geisser, S. (1959). On methods in the analysis of profile data. Psychometrika, 24(2), 95–112. https://doi.org/10.1007/BF02289823
Hinkin, T. R., & Tracey, J. B. (1999). An analysis of variance approach to content validation. Organizational Research Methods, 2(2), 175–186. https://doi.org/10.1177/109442819922004
MacKenzie, S. B., Podsakoff, P. M., & Podsakoff, N. P. (2011). Construct measurement and validation procedures in MIS and behavioral research: Integrating new and existing techniques. MIS Quarterly, 35(2), 293–334. https://doi.org/10.2307/23044045