Item-Sort Content Validation: Anderson-Gerbing to Howard-Melloy to Colquitt
Source:vignettes/item-sort-validity.Rmd
item-sort-validity.RmdWhat this workflow answers
Item-sort pretests ask judges to assign candidate items to construct definitions. The workflow provides two related kinds of evidence:
- Definitional correspondence: are items assigned to their intended construct?
- Definitional distinctiveness: are items assigned to the intended construct more often than to a competing construct?
Anderson and Gerbing (1991) operationalized these ideas with Psa and Csv. Howard and Melloy (2016) clarified exact inference for the target-assignment count, particularly when more than two assignment alternatives are present. Colquitt et al. (2019) later supplied empirical interpretation norms based on 112 published scales.
These statistics do not establish the entire content-validity argument. In particular, they do not establish that the item pool comprehensively covers the construct domain.
A reproducible example
sort_dat <- data.frame(
  item = rep(c("A1", "A2", "A3", "B1", "B2", "B3"), each = 20),
  rater = rep(1:20, 6),
  target_construct = rep(c("A", "A", "A", "B", "B", "B"), each = 20),
  assigned_construct = c(
    rep("A", 18), rep("B", 2),
    rep("A", 16), rep("B", 4),
    rep("A", 13), rep("B", 7),
    rep("B", 18), rep("A", 2),
    rep("B", 17), rep("A", 3),
    rep("B", 14), rep("A", 6)
  )
)

fit <- sort_validity(sort_dat)
fit
#> <contentvalid_sort> Item-sort analysis
#> Items: 6 | Judges: 20 | Target constructs: 2
#> Test: Howard-Melloy exact target-count test (p0 = .50, alpha = .05)
#> Judges: naive, meaning drawn from the kind of people who will answer the
#> items.
#>
#> 4 of 6 items meet the exact target-assignment criterion.
#> Flagged for review: A3, B3
#>
#> Item-level evidence
#>   Item  Target  Decision  Judges  Psa      95% CI  Csv  Competitor       p
#>   A1    A       Retain     18/20  .90  [.70, .97]  .80  B           < .001
#>   A2    A       Retain     16/20  .80  [.58, .92]  .60  B             .006
#>   A3    A       Review     13/20  .65  [.43, .82]  .30  B             .132
#>   B1    B       Retain     18/20  .90  [.70, .97]  .80  A           < .001
#>   B2    B       Retain     17/20  .85  [.64, .95]  .70  A             .001
#>   B3    B       Review     14/20  .70  [.48, .85]  .40  A             .058
#>
#>   Judges: assignments to the target construct, out of the judges who sorted
#>   the item.
#>   95% intervals for proportions: Wilson score (the default). Newcombe (1998)
#>   compared seven methods and recommends score intervals over the Wald
#>   interval. An interval reflects how few ratings an item received, not whether
#>   the right people rated it.
#>
#> Scale-level Colquitt benchmarks
#>   Target  Items  Mean Psa  Psa level  Mean Csv  Csv level
#>   A           3       .78  Moderate        .57  Moderate
#>   B           3      .817  Moderate        .63  Strong
#>   Benchmark set: Overall (not correlation-normed)
#>   These bands come from tasks with three definitions (one focal, two
#>   orbiting); judges here used 2 (set `n_constructs` if more were offered), so
#>   the comparison is approximate. This is a contentvalidR caution: Colquitt et
#>   al. do not discuss other numbers.
#>
#>   Colquitt labels are empirical percentile norms derived from scale-level
#>   averages, not universal cutoffs or automatic scale-retention rules. They
#>   place a scale against published scales. Psa and Csv sit on different scales,
#>   so their values cannot be compared with each other; their labels can,
#>   because each is a percentile position among published scales.
#>
#> What these columns mean
#>   Psa -- Proportion of Substantive Agreement. Share of judges who put the item
#>       in the construct it was written for (0 to 1; higher is stronger).
#>   95% CI -- Interval for Psa. Wider when fewer judges sorted the item; the
#>       method is named above.
#>   Csv -- Coefficient of Substantive Validity. How much more often judges chose
#>       the intended construct than its closest rival (-1 to 1; 0 is a tie).
#>   Competitor -- Strongest competing construct. The construct other than the
#>       intended one that judges chose most often.
#>   p -- Howard-Melloy exact test. Probability of at least this many target
#>       assignments if each judge picked the target at rate p0; compare with
#>       alpha.
#>
#> What the decisions mean
#>   Retain -- met the exact target-assignment criterion.
#>   Review -- did not meet the exact target-assignment criterion; the competitor
#>       column shows where judges put it instead.
#>
#>   Full definitions: contentvalid_glossary(). To hide this key:
#>   options(contentvalidR.show_key = FALSE).
#>
#> A flag for review is not an automatic deletion decision. Use theory,
#> construct-domain coverage, item wording, and qualitative judge feedback
#> alongside these statistics.
#>
#> See summary(x) for the flagged items and content_report(x) for an APA table.
The item table is intentionally diagnostic rather than merely
numeric. A Review flag is not a command to delete an item.
The output reports the strongest competing construct so that researchers
can distinguish weak target correspondence from specific construct
overlap.
summary(fit)
#> <contentvalid_sort summary> Item-sort analysis
#> Retain: 4 of 6 | Review: 2 of 6
#>
#> Scale-level evidence
#>   Target  Items  Retain  Review  Mean Psa  Psa level  Mean Csv  Csv level
#>   A           3       2       1       .78  Moderate        .57  Moderate
#>   B           3       2       1      .817  Moderate        .63  Strong
#>
#>   Psa = proportion of substantive agreement; Csv = coefficient of substantive
#>   validity (Anderson & Gerbing, 1991).
#>   A: Mean Psa and mean Csv both fall in the Moderate band of published scales
#>     (Colquitt et al., 2019). A contentvalidR suggestion for that band: review
#>     the weaker items before finalizing. These bands come from tasks with three
#>     definitions (one focal, two orbiting); judges here used 2 (set
#>     `n_constructs` if more were offered), so the comparison is approximate.
#>     This is a contentvalidR caution: Colquitt et al. do not discuss other
#>     numbers.
#>   B: Mean Psa falls in the Moderate band and mean Csv in the Strong band of
#>     published scales (Colquitt et al., 2019). A contentvalidR suggestion for
#>     the lower band, Moderate: review the weaker items before finalizing. These
#>     bands come from tasks with three definitions (one focal, two orbiting);
#>     judges here used 2 (set `n_constructs` if more were offered), so the
#>     comparison is approximate. This is a contentvalidR caution: Colquitt et
#>     al. do not discuss other numbers.
#>
#> Flagged
#>   Item  Target  Decision  Psa  Csv  Competitor     p
#>   A3    A       Review    .65  .30  B           .132
#>   B3    B       Review    .70  .40  A           .058
#>
#>   p = Howard-Melloy exact test of the target assignments.
#>   - A3 (Review): The target was at least as common as any competitor but did
#>     not meet the exact retention criterion (strongest competitor: B); review
#>     before deciding whether to revise or remove the item.
#>   - B3 (Review): The target was at least as common as any competitor but did
#>     not meet the exact retention criterion (strongest competitor: A); review
#>     before deciding whether to revise or remove the item.
#>
#> Interpret scale norms and item flags alongside theory, domain coverage, and
#> qualitative feedback. This analysis does not by itself establish
#> comprehensiveness or the full content-validity argument.
#>
#> See summary(x)$reviewed_items for the flagged items as a data frame.
Item-level inference: Howard-Melloy
The default exact test asks whether the target-assignment probability
exceeds .50. At N = 20 and
alpha = .05, an item needs 15 target assignments to meet
the one-sided exact criterion.
csv_binom_test(n_c = 15, N = 20)
#> <contentvalid_binom> Howard-Melloy exact test (one-sided)
#>
#> The item meets the exact target-assignment criterion.
#> 15 of 20 judges assigned the item to its target construct (Psa = .75). If each
#> judge chose the target with probability p0 = .50, a count this high has
#> probability p = .021.
#> At alpha = .05 an item needs at least 15 of 20.
#> One-sided 95% CI for the target rate: [.54, 1.00].
#>
#> See as.data.frame(x) for the test as one row.
csv_binom_test(n_c = 14, N = 20)
#> <contentvalid_binom> Howard-Melloy exact test (one-sided)
#>
#> The item does not meet the exact target-assignment criterion.
#> 14 of 20 judges assigned the item to its target construct (Psa = .70). If each
#> judge chose the target with probability p0 = .50, a count this high has
#> probability p = .058.
#> At alpha = .05 an item needs at least 15 of 20.
#> One-sided 95% CI for the target rate: [.49, 1.00].
#>
#> See as.data.frame(x) for the test as one row.
sort_validity() therefore uses Retain
to mean “meets this exact statistical screening criterion” and
Review to mean “does not meet it.” Revision or removal
remains a substantive decision.
Scale-level interpretation: Colquitt et al. (2019)
Colquitt et al. did not create their interpretation bands from
individual item values. They averaged Psa and Csv across the items in
each of 112 scales and then created empirical percentile bands.
sort_validity() follows that design: Howard-Melloy is used
item by item, while Colquitt interpretation is reported for each target
scale’s mean Psa and mean Csv.
The default uses the overall norms:
colquitt_benchmarks("psa")
#> <contentvalid_colquitt_norms> Benchmarks for Psa
#> Colquitt et al. (2019). Benchmark set: Overall (not correlation-normed).
#>
#>   Band         Percentile  Minimum
#>   Very Strong  80th-99th       .91
#>   Strong       60th-79th       .82
#>   Moderate     40th-59th       .72
#>   Weak         20th-39th       .39
#>   Lack of      0th-19th       none
#>
#> A scale-level mean at or above a band's minimum falls in that band. The bands
#> are percentiles of published scales, not validity cutoffs.
#>
#> See as.data.frame(x) for the unrounded values.
colquitt_benchmarks("csv")
#> <contentvalid_colquitt_norms> Benchmarks for Csv
#> Colquitt et al. (2019). Benchmark set: Overall (not correlation-normed).
#>
#>   Band         Percentile  Minimum
#>   Very Strong  80th-99th       .81
#>   Strong       60th-79th       .61
#>   Moderate     40th-59th       .51
#>   Weak         20th-39th       .05
#>   Lack of      0th-19th       none
#>
#> A scale-level mean at or above a band's minimum falls in that band. The bands
#> are percentiles of published scales, not validity cutoffs.
#>
#> See as.data.frame(x) for the unrounded values.
The labels—Very Strong, Strong, Moderate, Weak, and Lack of—are percentile bands relative to published scales, not universal validity cutoffs.
Correlation-conditional norms
Colquitt et al. showed that Psa/Csv depend partly on how similar the focal scale is to its orbiting scales. If substantive data provide an average focal-orbiting correlation, supply it to the workflow. With multiple focal scales, use a named vector.
fit_normed <- sort_validity(
  sort_dat,
  orbiting_r = c(A = .42, B = .28)
)
fit_normed$scale_summary[, c("target", "orbiting_r", "psa_strength",
                             "csv_strength")]
#>   target orbiting_r psa_strength csv_strength
#> 1      A       0.42     Moderate     Moderate
#> 2      B       0.28         Weak         Weak
# The benchmark set behind each target's labels
writeLines(paste0(fit_normed$scale_summary$target, ": ",
                  fit_normed$scale_summary$benchmark_set))
#> A: More moderate focal-orbiting correlation (.35-.50)
#> B: Weaker focal-orbiting correlation (r <= .34)
The conditional panels are:
-
.34or below: weaker focal-orbiting correlation; -
.35to.50: more moderate correlation; -
.51or above: stronger correlation.
A given Csv can be more impressive when the focal and orbiting constructs are closely related, so the appropriate norm can change the descriptive category.
Judge type matters
Anderson and Gerbing advocated naïve judges representative of the population of interest, and Colquitt et al.’s norms were generated with that kind of judge. Their criteria should not simply be transferred to expert panels.
expert_fit <- sort_validity(sort_dat, judge_type = "expert")
summary(expert_fit)
#> <contentvalid_sort summary> Item-sort analysis
#> Retain: 4 of 6 | Review: 2 of 6
#>
#> Scale-level evidence
#>   Target  Items  Retain  Review  Mean Psa  Mean Csv
#>   A           3       2       1       .78       .57
#>   B           3       2       1       .82       .63
#>
#>   Psa = proportion of substantive agreement; Csv = coefficient of substantive
#>   validity (Anderson & Gerbing, 1991).
#>   A, B: Colquitt benchmark labels are not applied because the analysis was
#>     marked as using expert judges.
#>
#> Flagged
#>   Item  Target  Decision  Psa  Csv  Competitor     p
#>   A3    A       Review    .65  .30  B           .132
#>   B3    B       Review    .70  .40  A           .058
#>
#>   p = Howard-Melloy exact test of the target assignments.
#>   - A3 (Review): The target was at least as common as any competitor but did
#>     not meet the exact retention criterion (strongest competitor: B); review
#>     before deciding whether to revise or remove the item.
#>   - B3 (Review): The target was at least as common as any competitor but did
#>     not meet the exact retention criterion (strongest competitor: A); review
#>     before deciding whether to revise or remove the item.
#>
#> Interpret scale norms and item flags alongside theory, domain coverage, and
#> qualitative feedback. This analysis does not by itself establish
#> comprehensiveness or the full content-validity argument.
#>
#> See summary(x)$reviewed_items for the flagged items as a data frame.
The Psa/Csv statistics and item-level screening remain available, but
Colquitt normative labels are not applied: the scale-level table has no
level columns, and the summary says why. In
expert_fit$scale_summary the label columns are kept, as
NA.
Judge type also bears on the exact test. Its default null target
rate, p0 = .50, follows Howard and Melloy (2016), who
describe .50 as arbitrary and lenient. They suggest a higher value, such
as .60 or .75, when the alternative constructs are clearly different
from the target or the judges are subject-matter experts. Choose
p0 before the data are collected, and report it:
csv_binom_test(n_c = 15, N = 20, p0 = .60)
#> <contentvalid_binom> Howard-Melloy exact test (one-sided)
#>
#> The item does not meet the exact target-assignment criterion.
#> 15 of 20 judges assigned the item to its target construct (Psa = .75). If each
#> judge chose the target with probability p0 = .60, a count this high has
#> probability p = .126.
#> At alpha = .05 an item needs at least 17 of 20.
#> One-sided 95% CI for the target rate: [.54, 1.00].
#>
#> See as.data.frame(x) for the test as one row.
With a null rate of .60, 15 of 20 judges no longer meets the criterion.
Planning judge sample size
Use sort_power() to calculate the exact probability that
an item will reach the required target-assignment count under a
plausible true target-assignment probability.
sort_power(N = c(20, 30, 40), true_p = c(.60, .70, .80))
#> <contentvalid_sort_power> Item-sort planning
#> Retention rule: Howard-Melloy exact test (p0 = .50, alpha = .05)
#>
#>   Judges  Required  Minimum Psa  Power at .60  Power at .70  Power at .80
#>       20     15/20          .75           .13           .42           .80
#>       30     20/30          .67           .29           .73           .97
#>       40     26/40          .65           .32           .81           .99
#>
#> Required: target assignments an item needs to be retained. Minimum Psa: the
#> same as a proportion (Psa = proportion of substantive agreement). Power at a
#> value: the exact probability of reaching the required count if each judge
#> assigns the item to its target with that probability.
#>
#> See plot(x) for the power curve.
This is preferable to treating a rule such as “20-40 judges” as a
universal sample-size requirement. Power depends on the assumed
target-assignment probability, N, the null probability, and
alpha.
Plotting item evidence
The one-index views remain available:
plot(fit, metric = "psa")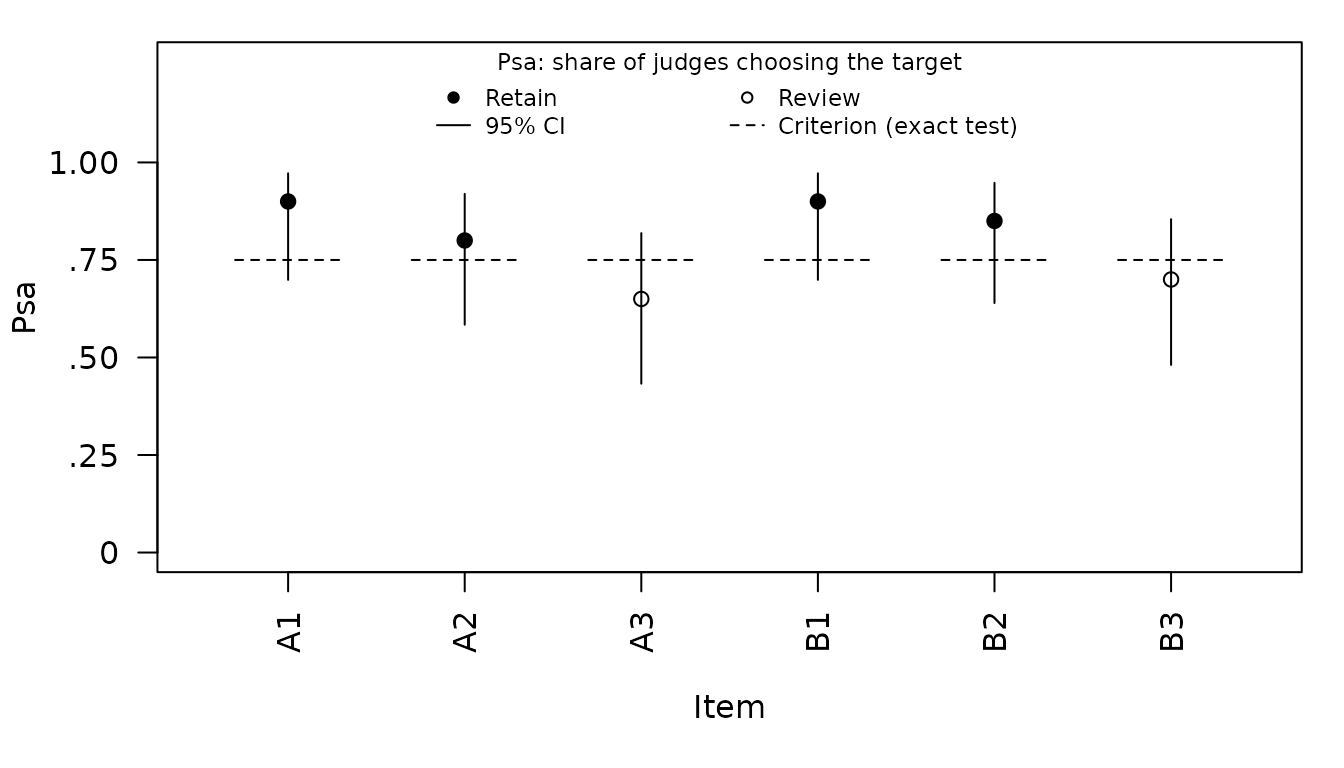
plot(fit, metric = "csv")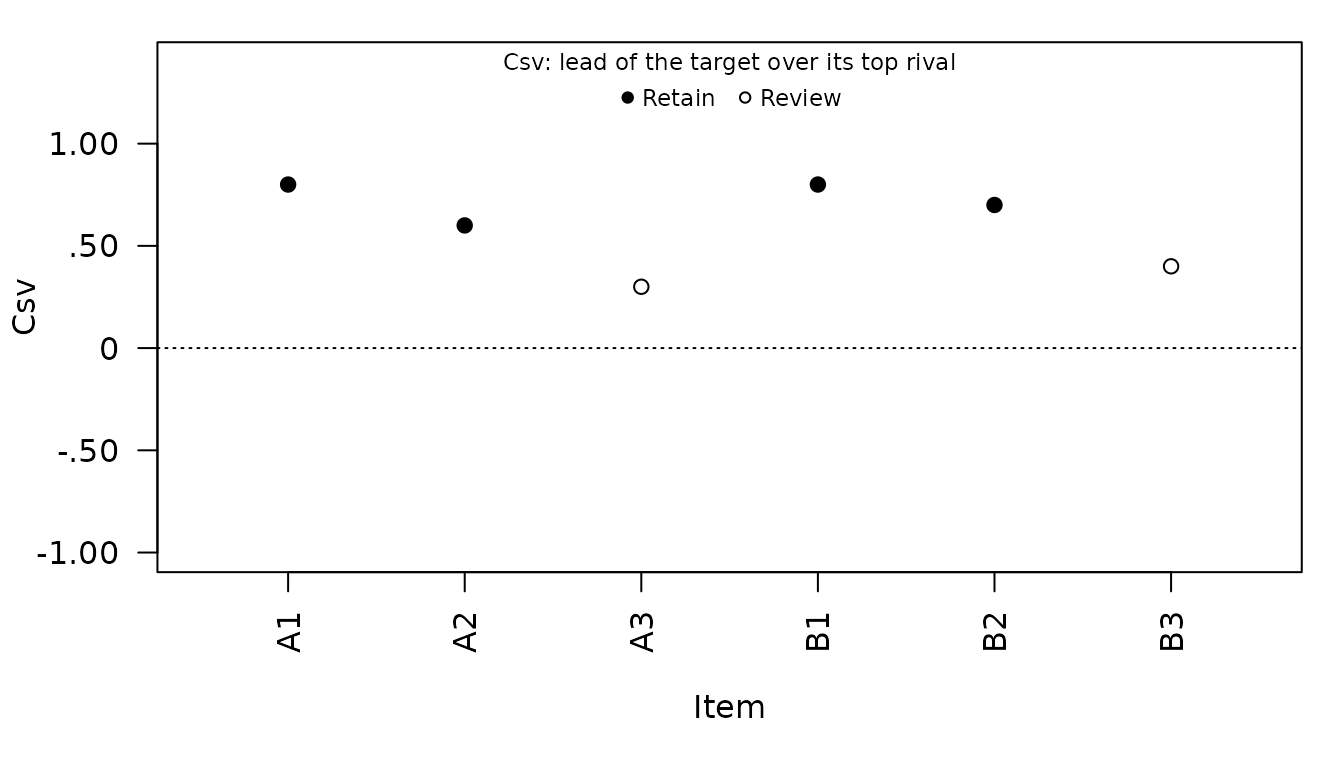
For diagnosis, the package also introduces a correspondence-distinctiveness evidence map:
plot(fit, type = "map")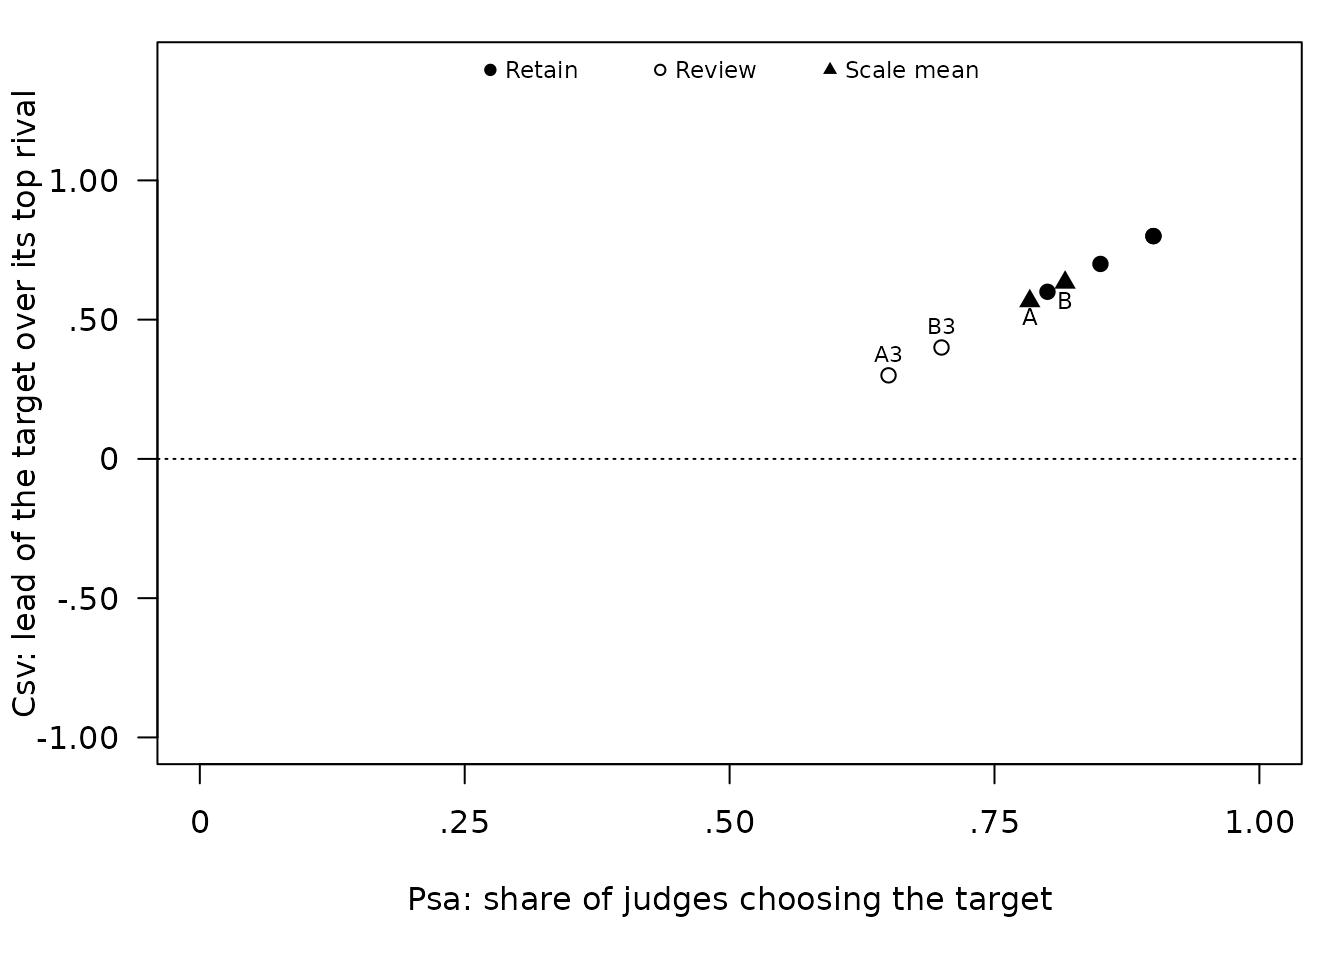
Psa and Csv are shown jointly, review items are labeled by default, and target- scale averages are added as triangles. This makes it easier to distinguish a correspondence problem (low Psa) from a construct-overlap problem (low or negative Csv). The map does not draw Colquitt cutoff regions across individual items because those empirical norms were constructed from scale-level averages.
The exact planning object is also plottable:
plan <- sort_power(N = seq(10, 50, by = 5), true_p = c(.60, .70, .80))
plot(plan)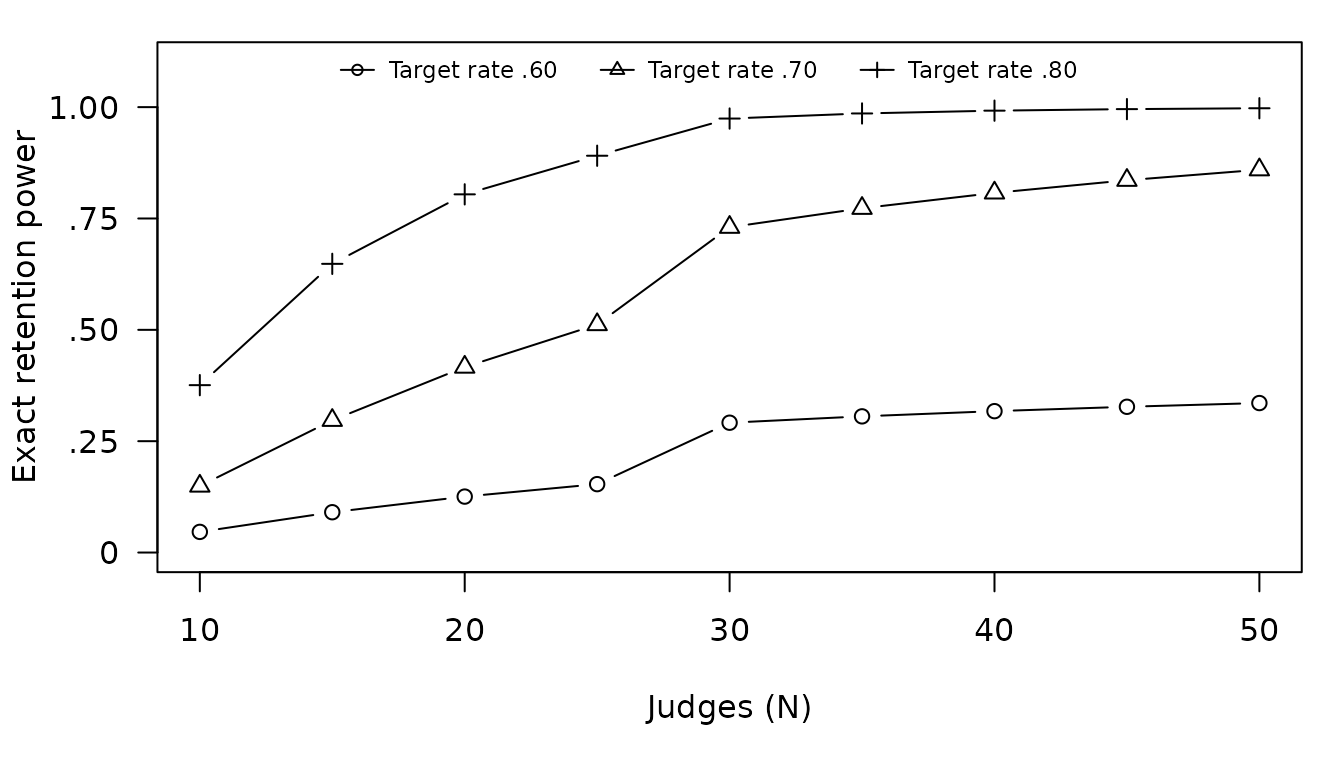
plot(plan, type = "critical")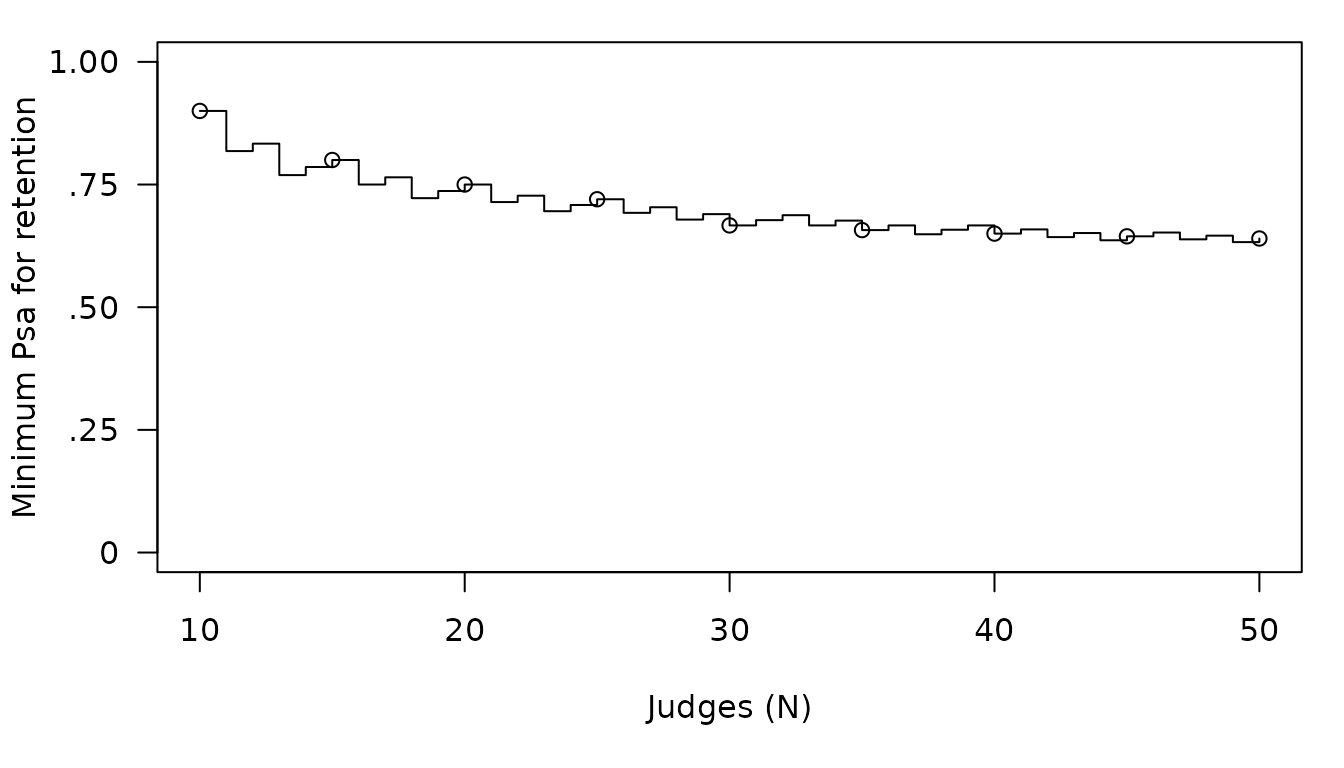
No conventional target-power line is imposed unless the analyst supplies one.
Earlier rules, for comparison only
contentvalidR retains Anderson and Gerbing’s Psa and Csv
indices but does not offer their critical-Csv rule as a way to decide.
Howard and Melloy (2016) showed that the older rule is appropriate for
the original two-choice case but becomes miscalibrated when it is
applied to sorts with more than two construct choices. Their revised
target-count procedure agrees with the older logic in the two-choice
case and is applicable to the broader designs now used in practice.
The earlier rules are still worth seeing, the way a methods course
reports eta-squared beside omega-squared. legacy = TRUE
prints them beside the decision, without changing it. In the
two-construct sort above, every judge who misses the target picks the
one other construct, and the two rules agree on every item. The
package’s shipped example has three constructs:
three <- read.csv(
  system.file("extdata", "sort_example.csv", package = "contentvalidR"),
  stringsAsFactors = FALSE
)
old <- options(contentvalidR.show_key = FALSE)
sort_validity(three, legacy = TRUE)
#> <contentvalid_sort> Item-sort analysis
#> Items: 6 | Judges: 20 | Target constructs: 3
#> Test: Howard-Melloy exact target-count test (p0 = .50, alpha = .05)
#> Judges: naive, meaning drawn from the kind of people who will answer the
#> items.
#>
#> 4 of 6 items meet the exact target-assignment criterion.
#> Flagged for review: B2, C2
#>
#> Item-level evidence
#>   Item  Target  Decision  Judges  Psa      95% CI  Csv  Competitor       p
#>   A1    A       Retain     18/20  .90  [.70, .97]  .85  B; C        < .001
#>   A2    A       Retain     15/20  .75  [.53, .89]  .60  B             .021
#>   B1    B       Retain     17/20  .85  [.64, .95]  .75  A             .001
#>   B2    B       Review     13/20  .65  [.43, .82]  .40  A             .132
#>   C1    C       Retain     18/20  .90  [.70, .97]  .85  A; B        < .001
#>   C2    C       Review     14/20  .70  [.48, .85]  .50  B             .058
#>
#>   Judges: assignments to the target construct, out of the judges who sorted
#>   the item.
#>   95% intervals for proportions: Wilson score (the default). Newcombe (1998)
#>   compared seven methods and recommends score intervals over the Wald
#>   interval. An interval reflects how few ratings an item received, not whether
#>   the right people rated it.
#>
#> Scale-level Colquitt benchmarks
#>   Target  Items  Mean Psa  Psa level  Mean Csv  Csv level
#>   A           2       .83  Strong          .73  Strong
#>   B           2       .75  Moderate        .58  Moderate
#>   C           2       .80  Moderate        .68  Strong
#>   Benchmark set: Overall (not correlation-normed)
#>
#>   Colquitt labels are empirical percentile norms derived from scale-level
#>   averages, not universal cutoffs or automatic scale-retention rules. They
#>   place a scale against published scales. Psa and Csv sit on different scales,
#>   so their values cannot be compared with each other; their labels can,
#>   because each is a percentile position among published scales.
#>
#> Earlier methods, for comparison (not used for the decision)
#>   Item  Decision  Psa  Csv  A&G (1991)  Yao et al. (2008)  Extension*
#>   A1    Retain    .90  .85  Meets       Meets              Meets
#>   A2    Retain    .75  .60  Meets       Meets              Meets
#>   B1    Retain    .85  .75  Meets       Meets              Meets
#>   B2    Review    .65  .40  Below       Meets              Meets
#>   C1    Retain    .90  .85  Meets       Meets              Meets
#>   C2    Review    .70  .50  Meets       Meets              Meets
#>
#>   Anderson and Gerbing (1991): Csv of at least .50, their critical value for
#>   20 judges at alpha = .05 (Equations 5 and 6). Their critical value assumes
#>   every judge who misses the target picks the same rival. When those judges
#>   spread across several constructs, Csv can reach it with fewer target
#>   assignments than the exact test needs.
#>   Yao et al. (2008): Psa and Csv both at least .30, set for a four-domain sort
#>   where chance assignment is .25.
#>   Extension*: a contentvalidR extension, not a published rule. It carries Yao
#>   et al.'s reasoning to this sort's 3 constructs as chance plus .05, so Psa
#>   and Csv both at least .38 (1/3 + .05).
#>   The 3 constructs are the ones judges used. If more were offered, set
#>   `n_constructs`, since chance depends on the number offered.
#>   Agreement with the decision above: Anderson and Gerbing on 5 of 6 items, Yao
#>   et al. on 4 of 6, the extension on 4 of 6.
#>   Csv counts only the single most-chosen rival construct (Anderson & Gerbing,
#>   1991, p. 734). Pooling every other construct into it instead gives twice Psa
#>   minus one, a different index.
#>
#> A flag for review is not an automatic deletion decision. Use theory,
#> construct-domain coverage, item wording, and qualitative judge feedback
#> alongside these statistics.
#>
#> See summary(x) for the flagged items and content_report(x) for an APA table.
options(old)
Look at C2. Fourteen of 20 judges chose its target, one short of the 15 the exact test needs, so the decision is Review. Anderson and Gerbing’s rule passes it: their critical Csv of .50 assumes the six judges who missed the target all chose one rival, but here they split, so Csv reaches .50 anyway. That is the miscalibration in miniature. Yao et al.’s (2008) .30 cutoffs pass every item, because they were set for four domains, where chance is .25; with three constructs, chance is already above .30.
The column marked Extension* is not a published rule. It
is this package’s extension of Yao et al.’s reasoning to any number of
constructs, chance plus .05, which gives their .30 for four constructs
and .38 for these three, and the printout labels it that way. Chance
depends on how many constructs judges were offered, not how many they
used, so give n_constructs when some construct drew no
assignments.
Reporting
A useful report should include:
- who the judges were and why they fit the intended design;
- the focal and orbiting constructs and their definitions;
- the number of judges and missing assignments;
- item-level Psa, Csv, target counts, strongest competitors, and exact decisions;
- target-scale mean Psa/Csv and the Colquitt norm set used;
- focal-orbiting correlations if conditional norms were used; and
- the substantive reasoning behind any revisions or removals.
References
Anderson, J. C., & Gerbing, D. W. (1991). Predicting the performance of measures in a confirmatory factor analysis with a pretest assessment of their substantive validities. Journal of Applied Psychology, 76(5), 732–740. https://doi.org/10.1037/0021-9010.76.5.732
Colquitt, J. A., Sabey, T. B., Rodell, J. B., & Hill, E. T. (2019). Content validation guidelines: Evaluation criteria for definitional correspondence and definitional distinctiveness. Journal of Applied Psychology, 104(10), 1243–1265. https://doi.org/10.1037/apl0000406
Howard, M. C., & Melloy, R. C. (2016). Evaluating item-sort task methods: The presentation of a new statistical significance formula and methodological best practices. Journal of Business and Psychology, 31(1), 173–186. https://doi.org/10.1007/s10869-015-9404-y
Yao, G., Wu, C.-H., & Yang, C.-T. (2008). Examining the content validity of the WHOQOL-BREF from respondents’ perspective by quantitative methods. Social Indicators Research, 85(3), 483–498. https://doi.org/10.1007/s11205-007-9112-8